The Data-Centric Future of AI Infrastructure
A comprehensive review highlights how data governance, privacy, and infrastructure will shape the next era of AI innovation.
In May 2025, as global AI development approached a critical juncture defined by escalating computational demands and tightening data regulations, a comprehensive review published on arXiv offered a timely reassessment of the field’s trajectory. Titled Data-Driven Breakthroughs and Future Directions in AI Infrastructure: A Comprehensive Review (arXiv:2505.16771), the paper by Beyazit Bestami Yuksel and Ayse Yilmazer Metin distills fifteen years of artificial intelligence progress into a coherent narrative centered not on algorithms or hardware alone, but on the evolving role of data infrastructure. Submitted just months before its formal publication in the Academic Platform Journal of Engineering and Smart Systems in January 2026, the 10-page analysis argues that the next era of AI innovation will be determined less by brute-force scaling and more by how effectively organizations manage, secure, and ethically govern data.
The significance of this shift cannot be overstated for executives, technical specialists, and founders operating across regulated industries—from healthcare to finance to industrial automation. As governments worldwide implement stricter data protection regimes like the EU’s AI Act and similar frameworks in Asia and North America, the assumptions underpinning the last decade of AI growth are being challenged. The review provides a strategic framework for navigating this transition, identifying four major technological inflection points that reshaped AI development and outlining emerging paradigms designed to reconcile innovation with privacy and compliance.
The Four Pillars of Modern AI Infrastructure
The authors trace the evolution of AI through four interdependent breakthroughs, each amplifying the impact of the others. First was the widespread adoption of GPU-based training, which enabled parallel processing at scales previously unattainable. This shift, beginning around 2010, allowed deep neural networks to process vast datasets efficiently—laying the groundwork for what would become modern machine learning.
The second pivotal moment came with the release of ImageNet in 2009 and its subsequent use in the ImageNet Large Scale Visual Recognition Challenge. This marked a decisive turn toward data-centric AI, where model performance became directly correlated with dataset size, quality, and annotation rigor. “The availability of large, well-curated datasets,” the paper notes, “transformed algorithmic research from theoretical exploration to empirical engineering.” ImageNet demonstrated that better data could outperform architectural novelty—a lesson that continues to inform training strategies today.
The third milestone was the introduction of the Transformer architecture in 2017. By simplifying model design and enabling self-attention mechanisms, Transformers drastically improved training efficiency and scalability across modalities. Unlike earlier recurrent or convolutional models, Transformers could handle long-range dependencies in text, audio, and vision tasks with fewer computational bottlenecks. This architectural streamlining coincided with—and accelerated—the rise of foundation models.
The fourth and most consequential development was the GPT series, particularly GPT-3 and its successors, which showcased the emergent capabilities of scale. These models revealed that increasing both data volume and parameter count led to qualitative leaps in reasoning, few-shot learning, and cross-domain generalization. However, the paper cautions against interpreting these gains as purely computational. Instead, it frames them through statistical learning theory, emphasizing reductions in sample complexity and improvements in data efficiency as key enablers of scalability.
From Data Abundance to Data Constraints
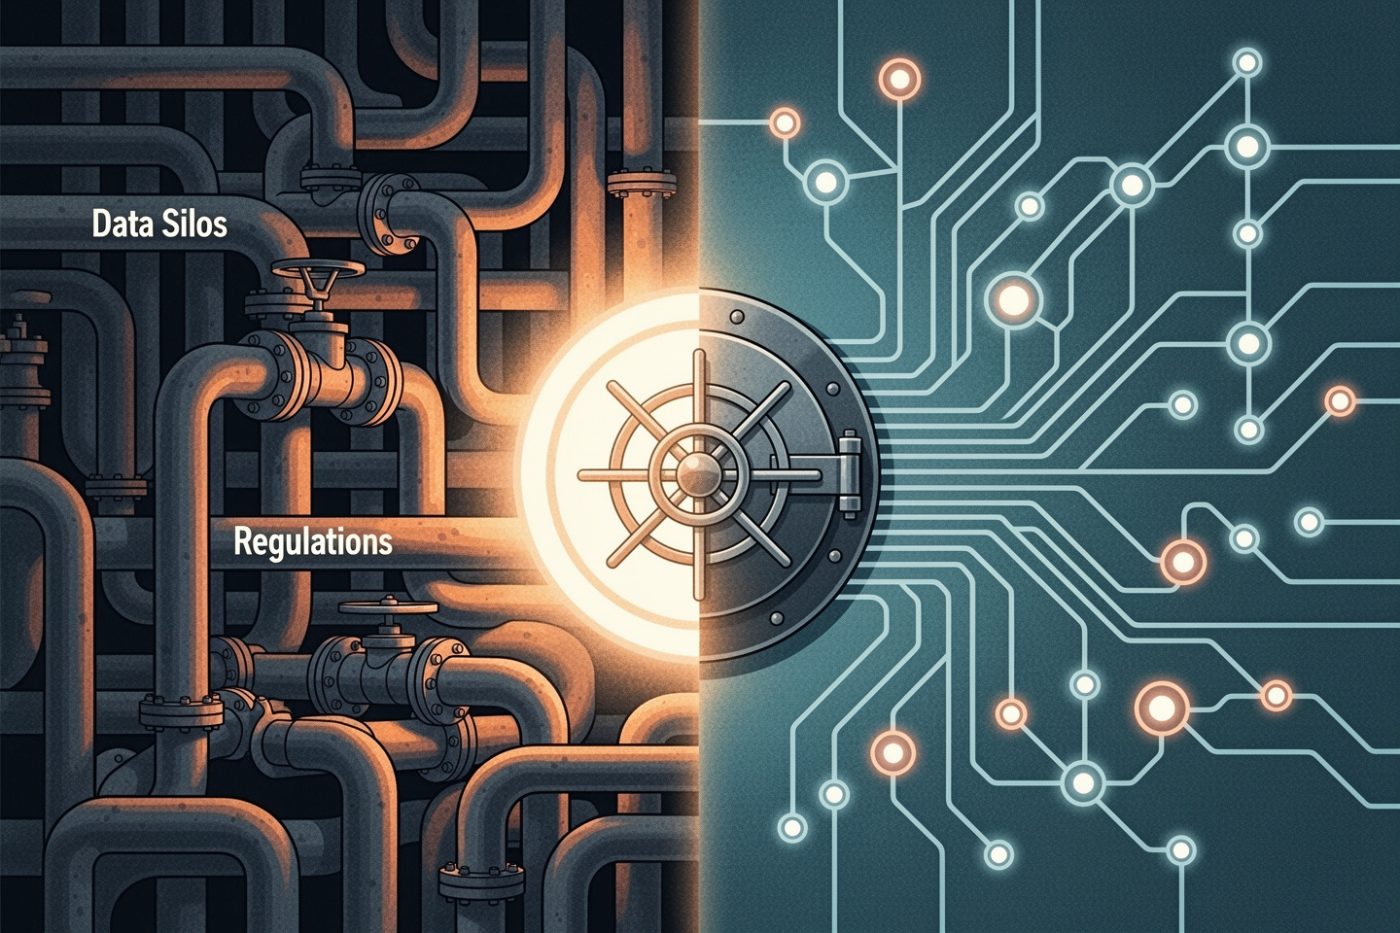
Despite these advances, the authors identify a growing tension between the data-hungry nature of contemporary AI and the rising barriers to data access. Regulatory restrictions, corporate data silos, and public concern over surveillance have created an environment where acquiring high-quality, real-world datasets is increasingly difficult. In response, the review evaluates several emerging solutions aimed at decoupling model performance from unrestricted data collection.
Federated learning emerges as one of the most promising approaches, allowing models to be trained across decentralized devices or institutions without centralizing raw data. The technique has seen practical deployment in mobile keyboard prediction and medical imaging consortia, where patient privacy laws prohibit data sharing. However, the paper acknowledges limitations: federated systems often suffer from slower convergence, higher communication overhead, and vulnerability to adversarial attacks if not properly secured.
Privacy-enhancing technologies (PETs) such as differential privacy, homomorphic encryption, and secure multi-party computation are also assessed. While theoretically robust, the authors note that many PETs remain computationally expensive and challenging to integrate into existing ML pipelines. For instance, differentially private stochastic gradient descent can reduce model accuracy by up to 10–15% on standard benchmarks, raising trade-offs between utility and compliance.
A more conceptual innovation proposed in the review is the “data site” paradigm—an institutional and technical framework where data remains under the control of its custodian, while authorized models are executed within audited, isolated environments. Analogous to cleanrooms in advertising technology, data sites aim to enable collaborative research without transferring sensitive information. Pilot implementations in European health data networks suggest feasibility, though standardization and interoperability remain unresolved challenges.
Synthetic and Mock Data: Promise and Pitfalls
With real-world data access constrained, synthetic and mock datasets have gained attention as alternatives for training and testing. The review examines their utility across domains, noting successes in autonomous vehicle simulation, financial fraud detection, and industrial IoT monitoring. Generative models, including diffusion architectures and large language models, now produce highly realistic synthetic data that preserves statistical properties while minimizing re-identification risks.
Yet the authors issue a strong caveat: synthetic data is not a panacea. They highlight studies showing that models trained exclusively on synthetic inputs can exhibit degraded performance when deployed in real-world settings, particularly in edge cases not captured during generation. Moreover, there is a risk of “synthetic bias”—where artifacts introduced during generation propagate through downstream models, leading to systemic errors.
Mock data, used primarily for software testing and pipeline validation, faces even steeper limitations. While useful for debugging, mock datasets lack the complexity and noise patterns of authentic data, making them unsuitable for performance benchmarking. The paper recommends treating both synthetic and mock data as supplements rather than replacements, advocating for hybrid training approaches that combine limited real data with carefully validated synthetic augmentations.
Strategic Implications for Global Organizations
For international stakeholders, the review offers a clear directive: future competitiveness in AI will hinge on data governance as much as technical capability. The authors argue that enterprises must shift from a compute-first mindset to a data-intelligent strategy—one that prioritizes metadata management, lineage tracking, consent frameworks, and auditability. They cite examples from multinational banks and pharmaceutical firms that have begun restructuring their AI teams around data stewardship roles, integrating legal and compliance experts into model development workflows.
The paper also calls for greater investment in open, interoperable data standards and shared infrastructure, particularly in sectors where data fragmentation impedes progress. Drawing parallels to cloud computing’s early days, the authors suggest that modular, composable data platforms—akin to Kubernetes for data—could lower entry barriers and foster collaboration without compromising security.
Looking ahead, Yuksel and Yilmazer Metin predict that the next wave of AI innovation will emerge not from labs with the most GPUs, but from organizations that master the alignment of technical systems with ethical and regulatory constraints. “The bottleneck is no longer processing power,” they conclude. “It is trust.” As AI moves deeper into high-stakes applications—from clinical diagnostics to autonomous infrastructure—the ability to demonstrate responsible data practices may become the defining competitive advantage.
Sources
- [2505.16771] Data-Driven Breakthroughs and Future Directions in AI Infrastructure: A Comprehensive Review
- [论文评述] Data-Driven Breakthroughs and Future Directions in AI Infrastructure: A Comprehensive Review
- [PDF] Data-Driven Breakthroughs and Future Directions in AI Infrastructure: A Comprehensive Review | Semantic Scholar
- [PDF] Data-Driven Breakthroughs and Future Directions in AI Infrastructure
- Harnessing Large Language Models in the Construction Industry: A Comprehensive Review of Applications, Challenges, and Future Directions
Written by an AI editorial process from the sources above. Errors may occur.
Newsletter
Get the AI news that matters
One short brief with the day's most important AI stories — written for professionals.
We send a confirmation link. No spam. Unsubscribe anytime.
Read next
AI Accelerates Drug Discovery from Concept to Clinic
Artificial intelligence is slashing development timelines and costs in pharmaceutical R&D, with AI-designed drugs now entering clinical trials in record time.
27 Sep 2026
Google Moves Gemini Team Under DeepMind Leadership
Google integrates its consumer AI app team into DeepMind to accelerate generative AI development and streamline research-to-product pipelines.
25 Sep 2026
AI in Drug Discovery: From Target ID to Clinical Trials
Artificial intelligence is accelerating drug discovery, but clinical validation remains the final frontier.
24 Sep 2026