AMD Challenges NVIDIA with New Datacenter GPU
AMD's MI350X GPU enters the AI hardware race with superior memory and pricing, but faces an uphill battle against NVIDIA's software dominance and ecosystem lock-in.
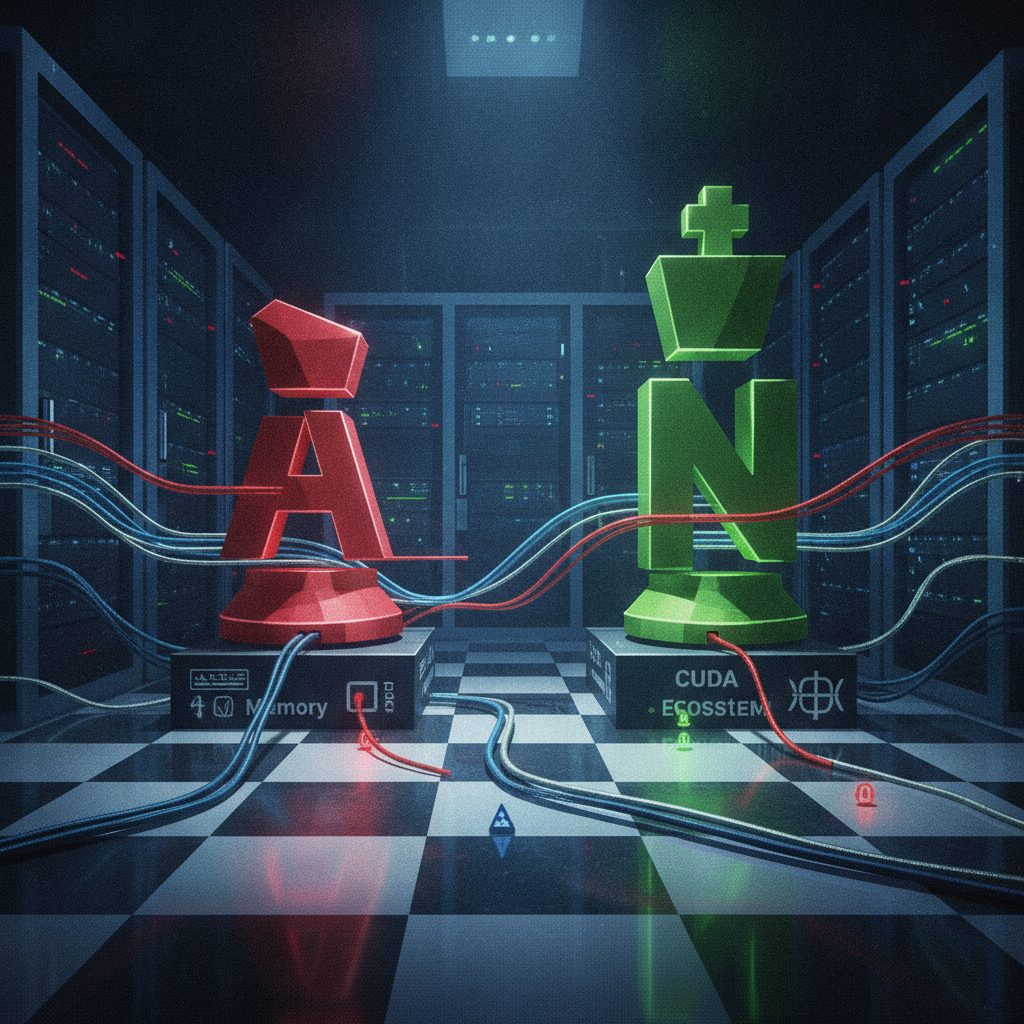
In a direct challenge to NVIDIA’s dominance in AI infrastructure, AMD has unveiled the MI350X, a datacenter GPU boasting 288GB of HBM3E memory—significantly more than NVIDIA’s flagship B200, which offers 192GB. With generative AI models growing exponentially in size, memory capacity has become a critical bottleneck, and AMD is betting that its new chip will attract hyperscalers and enterprises struggling with NVIDIA’s supply constraints and premium pricing. While the MI350X matches or exceeds the B200 in raw specifications, including 8 TB/s of memory bandwidth and approximately 4,600 TFLOPS of FP8 compute, analysts caution that hardware alone won’t dislodge NVIDIA’s entrenched position. The real battle lies in software, where CUDA’s maturity continues to deliver higher real-world performance and developer adoption.
This matters because AI infrastructure decisions now shape competitive advantage at scale. For C-suite executives and AI founders, the choice between NVIDIA and AMD isn’t just technical—it’s strategic. While NVIDIA is projected to capture about 80% of the $242 billion AI accelerator market by 2026, generating an estimated $193.7 billion in revenue, AMD’s Instinct line is expected to secure 5–7%, or $7–8 billion, according to Silicon Analysts. That gap reflects not just hardware differences, but the depth of NVIDIA’s ecosystem. Yet with cloud providers like Microsoft Azure, Meta, Oracle Cloud, and hardware partners such as Dell now supporting AMD’s GPUs, the door is open for meaningful competition—especially in inference workloads and memory-intensive applications where the MI350X’s 288GB capacity provides a tangible edge.
Specs and Pricing: AMD’s Hardware Edge
The AMD MI350X, built on a 4nm process and featuring a TDP of around 1,000W, is designed for large-scale AI inference and high-performance computing (HPC). Its 288GB of HBM3E memory gives it a 50% capacity advantage over NVIDIA’s B200, making it particularly attractive for running massive language models like Llama 4 Maverick, which exceeds 400 billion parameters. Memory bandwidth is on par with the B200 at 8 TB/s, and FP8 compute performance reaches approximately 4,600 TFLOPS—slightly above the B200’s 4,500 TFLOPS. Both GPUs use advanced interconnects: AMD relies on its Infinity Fabric, while NVIDIA deploys NVLink 5, capable of 1.8 TB/s of inter-GPU bandwidth, a key differentiator for multi-GPU scaling.
Pricing further strengthens AMD’s value proposition. The MI350X is estimated to cost between $20,000 and $30,000, undercutting the B200’s $30,000–$40,000 range. In cloud deployments, the MI350X starts at approximately $2.01 per hour, offering a lower entry point for startups and mid-sized firms. “AMD is clearly targeting cost sensitivity and supply availability,” says Karl Freund, CEO of Cambrian AI Research. “They’re not trying to beat NVIDIA at their own game—they’re changing the game by focusing on memory and price.”
The Software Gap: Where NVIDIA Still Leads
Despite AMD’s hardware gains, real-world performance remains tilted in NVIDIA’s favor. According to Silicon Analysts, NVIDIA GPUs achieve 50–55% model FLOPS utilization (MFU)—a measure of how efficiently a model uses theoretical compute capacity—compared to AMD’s ~45%. That 10–25% gap stems largely from software maturity. NVIDIA’s CUDA platform, developed over 15 years, offers robust libraries, debugging tools, and broad framework support, enabling developers to optimize models with minimal friction.
AMD’s ROCm (Radeon Open Compute) stack, while improving with the upcoming ROCm 7.x release, still lacks the breadth and stability of CUDA. “ROCm has made progress, but it’s not plug-and-play for most AI teams,” says Matt Kimball, analyst at Moor Insights & Strategy. “Companies running mission-critical training workloads can’t afford the engineering overhead of porting models and troubleshooting compatibility issues.” This software inertia means that even when AMD’s hardware is available, many organizations default to NVIDIA to avoid delays and unpredictability.
The interconnect architecture also plays into this. While both GPUs deliver similar memory bandwidth, NVIDIA’s NVLink 5 enables faster and more efficient communication across GPU clusters, which is essential for distributed training. AMD’s Infinity Fabric, though capable, hasn’t demonstrated the same level of scalability in large deployments. “For a 1,000-GPU cluster training a foundation model, NVLink’s bandwidth and low latency are decisive,” Kimball adds.
Hyperscaler Adoption and Market Realities
Despite these challenges, AMD is gaining traction. Microsoft Azure has integrated MI300X GPUs into its cloud infrastructure, and Meta has signaled interest in diversifying its AI hardware suppliers to mitigate supply chain risks. Oracle Cloud and Dell are also offering systems equipped with AMD Instinct accelerators. This support is driven in part by persistent shortages of NVIDIA’s H100 and B200 chips, which have left many AI teams waiting months for capacity.
“We’re seeing real movement from hyperscalers who want to avoid over-reliance on a single vendor,” says Freund. “AMD isn’t winning on performance yet, but they’re winning on availability and cost.” This shift is particularly evident in inference workloads, where the MI350X’s large memory footprint allows for efficient serving of large models without constant data swapping. For companies running LLMs in production, that can translate into lower latency and higher throughput.
Still, AMD’s market share remains modest. Even with projected growth, its 5–7% slice of the 2026 AI accelerator market pales next to NVIDIA’s dominance. And while the MI350X closes the compute gap, it doesn’t eliminate the ecosystem advantages that have made NVIDIA the de facto standard. “AMD is a credible alternative, not a replacement,” says Kimball. “They’re forcing NVIDIA to innovate and maybe even moderate prices, but they’re not displacing them.”
The Bigger Threat to NVIDIA May Not Be AMD
Ironically, the most significant long-term challenge to NVIDIA’s dominance may not come from AMD at all, but from custom AI accelerators developed in-house by cloud providers. Google’s TPU, AWS’s Trainium, and Microsoft’s Maia chip are all gaining share, particularly within their respective ecosystems. These ASICs are optimized for specific workloads and tightly integrated with internal software stacks, offering efficiency gains that general-purpose GPUs can’t match.
According to industry estimates, custom ASICs are growing faster in adoption than any other category of AI hardware. “The hyperscalers are building their own ladders and pulling them up behind them,” says Freund. “They’re using AMD as a stopgap, but their real play is vertical integration.” This trend could fragment the AI hardware market, reducing reliance on both NVIDIA and AMD for certain workloads.
AMD’s role, then, may be less about overtaking NVIDIA and more about sustaining competition. By offering a viable alternative, AMD pressures NVIDIA on pricing and supply, while giving enterprises leverage in procurement negotiations. “AMD’s success isn’t measured in market share alone,” says Kimball. “It’s measured in how much it forces the entire industry to move faster.”
As the MI350X enters early deployment in 2025, real-world benchmarks will be critical. Independent performance data is still limited, and the maturity of ROCm 7.x will determine whether AMD can close the software gap. For now, NVIDIA remains the leader in both hardware and ecosystem, but the datacenter GPU race is no longer a one-horse contest. With memory capacity, pricing, and supply becoming decisive factors, AMD has positioned itself as the pragmatic alternative—especially for organizations that can’t wait, or can’t pay, for NVIDIA’s premium.”
Sources
- AMD Goes After NVIDIA With New GPU For The Datacenter - Cambrian AI Research
- AMD Goes After NVIDIA With New GPU For The Datacenter
- AMD Takes On Nvidia with New GPU for AI
- Warning Shots Fired as AMD Announces New Data Center ...
- AMD Lays Out its Road Map to Erode NVIDIA's Dominance in ...
Written by an AI editorial process from the sources above. Errors may occur.
Newsletter
Get the AI news that matters
One short brief with the day's most important AI stories — written for professionals.
We send a confirmation link. No spam. Unsubscribe anytime.
Read next
Gemini's New AI Model Transforms Photo Editing with Multi-Turn Control
Google's Gemini 2.5 Flash Image enables precise, context-aware edits across multiple steps, advancing creative workflows for professionals.
27 Sep 2026
Autonomous AI Agents: The Rise of Digital Workforce
How self-reasoning AI systems are transforming business workflows and redefining automation across industries.
26 Sep 2026
Adobe Launches AI Video Generation in Creative Cloud
Adobe unveils Firefly Video Model and faster image generation, embedding AI deeply into professional creative workflows.
26 Sep 2026